Imagine a customer opening a shopping app and typing, “My order still hasn’t arrived, and I’m getting frustrated.” A basic search feature might look for the word order. An NLP-powered system can do more: recognize a delivery-related request, identify the customer’s frustration, retrieve the relevant order information, and respond with an appropriate next step.
That difference matters for businesses. According to Salesforce’s State of Service research, 43% of consumers say a poor customer service experience will prevent them from making a repeat purchase. Mobile apps that make support easier and help businesses understand customer feedback can contribute to a better customer experience.
Natural language processing (NLP) makes these experiences possible by helping software analyze human language, whether users type a message, speak a request, or leave a product review. But NLP is not a single feature that automatically understands everything. It is a collection of techniques, models, and application logic that work together.
This guide explains how NLP in mobile apps works, how chatbots interpret and respond to messages, how sentiment analysis extracts insights from feedback, and what businesses should consider when implementing these capabilities.
Key Takeaways
- NLP in mobile apps helps users interact with apps through natural language, powering chatbots, voice interfaces, intelligent search, and feedback analysis.
- Chatbots combine intent classification, entity extraction, and dialogue management to understand requests, maintain context, and guide users toward solutions.
- Sentiment analysis identifies customer opinions and recurring feedback themes, helping businesses spot issues and improve app experiences.
- LLMs and retrieval-augmented generation (RAG) support more flexible conversations and context-aware responses, but require reliable data sources and safeguards against inaccurate answers.
- On-device vs. cloud NLP depends on privacy requirements, processing power, connectivity, latency, and cost.
- Successful NLP implementation requires representative data, secure integrations, performance testing, and ongoing monitoring.
What Is NLP in Mobile Apps?
Natural language processing is a branch of artificial intelligence that enables software to process and analyze human language. It combines computational linguistics, machine learning, and statistical or neural models to identify patterns in text and speech.
According to Amazon Web Services’ overview of NLP, common NLP tasks include language translation, speech recognition, text classification, and information extraction.
In mobile applications, NLP allows users to interact with software using everyday language instead of relying entirely on menus, filters, or predefined commands.
For example, an NLP-powered banking app might interpret “Show me the payments I made last week” as a request to retrieve transactions within a specific date range. A fitness app might process a spoken question about a workout, while an ecommerce app could analyze reviews to identify recurring complaints about delivery or product quality.
Common NLP capabilities in mobile apps include:
- Intent classification: Identifying what a user wants to do, such as tracking an order or resetting a password.
- Named entity recognition (NER): Extracting relevant details, such as a product name, location, date, or order number.
- Semantic analysis: Interpreting meaning and relationships rather than relying only on exact keyword matches.
- Sentiment analysis: Estimating whether a message expresses positive, negative, or neutral sentiment.
- Language detection and translation: Identifying a user’s language and, where supported, translating content.
- Speech-to-text and text-to-speech: Converting spoken language into text and generating spoken output.
- Text summarization and keyword extraction: Condensing lengthy content and identifying important terms.
Businesses may use these capabilities individually or combine them into conversational AI, intelligent search, personalized recommendations, and automated feedback analysis. The appropriate combination depends on the app’s users, the task being automated, and the quality of the available data.
How Does NLP Work in a Mobile App?
NLP usually operates as a pipeline. The app captures a message, processes the input, determines its meaning, retrieves relevant information or selects an action, and then presents a response.
The exact sequence depends on the feature. A sentiment analysis tool may stop after classifying a review, while a customer service chatbot may need to retrieve account information and complete a transaction.
1. Collect and Prepare The User’s Input
The process begins when someone enters text or speaks into the app. If the input is spoken, an automatic speech recognition system may first convert the audio into text.
The application then prepares the input for analysis. Depending on the model and task, preprocessing may include:
- Normalizing text, such as standardizing certain character variations.
- Detecting the language.
- Splitting text into tokens, which may be words, subwords, or other units.
- Removing irrelevant formatting or handling emojis, punctuation, and spelling variations.
- Identifying incomplete, malformed, or unsupported input.
Traditional NLP pipelines may use stemming or lemmatization to reduce words to their root or dictionary form. Modern transformer models often rely on tokenization and learned representations instead, so these older preprocessing steps are not automatically necessary for every system.
Consider the message, “Where’s my package? It’s two days late!” The system must preserve the delivery-related meaning and the timing information. Removing words or punctuation indiscriminately could discard useful context, particularly for sentiment analysis.
2. Identify Intent, Entities, and Meaning
Once the input is prepared, the model analyzes what the user is communicating.
Intent classification assigns a likely purpose to the message. In a retail app, possible intents include tracking an order, requesting a refund, changing a delivery address, or asking about a product.
Named entity recognition extracts specific details. In “Track order 58214,” the system may identify “58214” as an order identifier. In “Book a table in Boston on Friday,” it may identify a location and date, although the application may still need to resolve which Friday the user means.
Semantic analysis helps the system interpret different phrases that express a similar request. “Where is my package?”, “Can you check my delivery?”, and “My order hasn’t arrived” may all relate to order tracking, even though they use different words.
Modern NLP models can also use context from earlier messages. However, context awareness must be implemented deliberately. A model may need conversation history, session state, or information from a connected business system to resolve references correctly.
3. Retrieve Information or Select An Action
Understanding a request does not necessarily mean the app has the information needed to answer it.
If a user asks about an order, the application may need to query an order management system or backend API. If the user asks a question about a product policy, it may search for an approved knowledge base.
This stage can involve several techniques:
- Keyword search: Finds documents containing matching terms.
- Semantic search: Retrieves content based on similarity in meaning.
- Embeddings: Represent text as numerical vectors that can be compared for semantic similarity.
- Vector databases: Store and search vector representations when an application needs retrieval at scale.
- Dialogue management: Determines what the system should do next, including whether to ask a follow-up question, retrieve data, or transfer the conversation to a human.
Retrieval-augmented generation (RAG) combines information retrieval with a generative model. Instead of relying only on what a language model learned during training, the system retrieves relevant information and supplies it as context for generating an answer.
For example, a support chatbot could retrieve the current return policy before answering a customer’s question. The quality of the response still depends on whether the retrieved information is relevant, current, and correctly used.
4. Generate and Deliver The Response
After the system identifies the required action or gathers relevant information, it produces an output.
A conventional NLP system may select a predefined response, populate a template, or return a structured result. An LLM-powered system may generate a natural-language answer based on the user’s message, conversation context, and retrieved information.
The app then displays the response or converts it into speech. Before a consequential action, such as issuing a refund or changing an account detail, the application should validate permissions, required fields, and business rules rather than trusting the model to make the decision on its own.
A simplified flow looks like this:
User input → preprocessing → intent and entity analysis → retrieval or action → response generation → validation and delivery
Not every app requires every stage. A review classifier may need only text input and a classification model, while a voice-based assistant may combine speech recognition, language understanding, retrieval, dialogue management, and speech synthesis.
How Do NLP-Powered Chatbots Understand and Respond to Users?
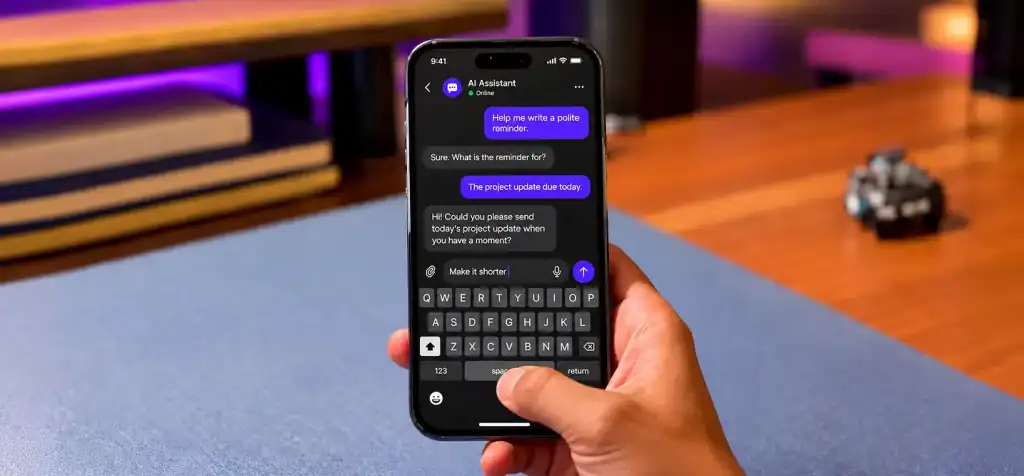
An NLP-powered chatbot converts conversational input into a task the application can handle. It may answer a question, retrieve account information, guide a user through a workflow, or route an issue to a human support agent.
The distinction is important: a chatbot does not automatically know a customer’s account details or business policies. It needs authorized access to the relevant systems and a reliable process for using the information it receives.
1. Intent Classification and Entity Extraction
Suppose a customer writes, “I need to return the blue jacket I ordered last Tuesday.”
The chatbot may identify:
- Intent: Start a return.
- Product: Blue jacket.
- Order timing: Last Tuesday.
- Potential missing information: The exact order, return eligibility, or reason for return.
The app can use these details to search for the relevant order. If multiple orders match, it should ask the customer to clarify rather than select one arbitrarily.
This combination of intent classification and entity extraction makes conversations more flexible than a fixed menu. It also helps the app collect the information required to complete a task.
Businesses evaluating chatbot use cases can explore these chatbot artificial intelligence examples to see how conversational systems can support different workflows.
2. Dialogue Management and Conversation Memory
Dialogue management controls the flow of a conversation. It tracks the current task, determines which information is missing, and decides whether to ask a follow-up question or proceed.
Conversation memory is related but distinct. It refers to information retained from previous turns or interactions, such as the order being discussed or the user’s selected preferences. This may be stored in session state, a database, a conversation history, or a combination of these, depending on the system’s needs.
For example:
User: “Where is my order?”
Chatbot: “I can check that. Which order are you asking about?”
User: “The one I placed on Monday.”
The chatbot needs to connect the second message to the original request. If the app cannot identify the order confidently, it should request another detail.
Conversation memory should not mean retaining every message indefinitely. Businesses need clear rules for data retention, access, consent, and deletion, particularly when conversations contain personal or financial information.
3. LLMs and Prompt Engineering
Large language models (LLMs) are trained on large collections of text and learn patterns that help them interpret and generate language. Many modern LLMs use transformer architectures, which process relationships between tokens to represent context.
Unlike a narrowly trained intent classifier, an LLM can handle a broader range of phrasing and generate flexible responses. However, a fluent answer is not necessarily a correct one. LLMs can misinterpret a request, invent details, or respond confidently when the available evidence is insufficient.
Prompt engineering involves structuring instructions and context to guide a model’s behavior. A well-designed prompt might specify the chatbot’s role, the approved information sources, the response format, and what to do when the answer is unknown.
Prompt engineering alone cannot guarantee factual accuracy. It works best alongside relevant data retrieval, output validation, permission checks, testing, and clear fallback behavior.
For businesses considering generative AI capabilities, this guide to integrating ChatGPT into a business provides a related starting point.
4. RAG and Semantic Search
A general-purpose language model may not know a company’s latest product availability, internal policies, or customer-specific account details. Retrieval-augmented generation can help by supplying relevant information at response time.
A typical RAG workflow works as follows:
- The user submits a question.
- The system converts the question into a search query or embedding.
- A retrieval component searches an approved knowledge base or document collection.
- Relevant passages are passed to the language model as context.
- The model generates an answer based on the available context.
- The application validates the response and presents it to the user.
A vector database may support semantic retrieval, but it is not required for every RAG implementation. Smaller or simpler applications may use other search approaches.
RAG also does not eliminate hallucinations. Poor retrieval, outdated documents, conflicting sources, or vague instructions can still produce incorrect answers. Businesses should evaluate retrieval quality and response faithfulness, and make it possible for the chatbot to acknowledge when the available evidence is insufficient.
LLM-based experiences are also part of the wider adoption of generative AI in mobile apps, where language generation may be combined with search, summarization, recommendations, or task automation.
How Does Sentiment Analysis Work in Mobile Apps?
Sentiment analysis uses NLP to estimate the attitude expressed in text. Businesses can apply it to app reviews, customer support conversations, survey responses, feedback forms, and other text-based interactions.
The output may classify a message as positive, negative, or neutral. More advanced systems may estimate sentiment strength, identify particular emotions, or assess opinions about individual aspects of a product or service.
As IBM explains in its overview of sentiment analysis, these systems help organizations examine large volumes of opinions and extract patterns that are difficult to identify manually.
1. From Raw Text to Sentiment Classification
Imagine a food delivery app receiving this review:
“The food was great, but the delivery took forever.”
A basic sentiment model might classify the review as mixed or neutral, depending on its labels and training data. A more useful system can distinguish the positive comment about food quality from the negative comment about delivery time.
A sentiment analysis pipeline may include:
- Text preparation: Handle formatting, language, emojis, spelling variations, and other input characteristics.
- Feature representation: Convert the text into features or learned representations the model can process.
- Classification: Predict sentiment labels or scores.
- Aggregation: Combine results across reviews, categories, time periods, or user segments.
- Reporting: Present trends to teams responsible for customer experience, operations, or product improvement.
The model might use a traditional machine learning classifier, a neural network, or an LLM-based approach. The best option depends on the data, languages, cost constraints, required latency, and acceptable error rate.
2. Aspect-Based Sentiment Analysis
Overall sentiment can hide the specific reason a customer is satisfied or dissatisfied. Aspect-based sentiment analysis (ABSA) addresses this by connecting opinions to particular features or aspects.
For example, a mobile app review might say:
“The interface is easy to use, but the latest update drains my battery.”
An aspect-based system could extract:
| Aspect | Sentiment |
| Interface usability | Positive |
| Battery consumption | Negative |
This gives product teams a clearer view of what users appreciate and what needs investigation. Similar analysis can separate opinions about delivery, pricing, customer support, reliability, or individual product features.
Aspect-based results should still be treated as model predictions, not unquestionable facts. Teams should inspect ambiguous cases and validate model performance against human-labeled examples.
3. Topic Modeling and Keyword Extraction
Sentiment analysis tells a business how feedback is expressed, but it does not always explain the main issues customers are discussing.
Keyword extraction identifies important terms or phrases, such as “login error,” “slow checkout,” or “battery drain.”
Topic modeling groups recurring themes across a collection of documents. Depending on the approach, it can help uncover themes that were not defined in advance. Other systems use predefined categories or text embeddings to group similar feedback.
For example, a team reviewing thousands of app comments might discover recurring complaints about failed logins, confusing navigation, or delayed notifications. The team can then investigate these themes instead of reading every comment individually.
Text summarization can condense the resulting feedback into a shorter report. However, summaries should preserve the source evidence and avoid presenting a small number of comments as representative of all users.
4. Turning Sentiment Data into Business Decisions
Sentiment analysis is most valuable when the findings lead to an appropriate action. Depending on the use case, a mobile app and its connected systems may:
- Flag negative feedback for human review.
- Identify recurring complaints after an app update.
- Track sentiment toward specific features or service categories.
- Summarize customer support conversations for service teams.
- Route urgent issues to the appropriate department.
- Compare feedback trends across app versions or customer segments.
Sentiment should not be treated as a complete measure of customer satisfaction. Sarcasm, mixed opinions, cultural differences, short messages, and missing context can affect model predictions. A negative message may also describe a problem without expressing a clear emotion.
When feedback needs to be connected to support records, a chatbot can work alongside CRM workflows. See how chatbot integration with CRM systems can connect conversational experiences with customer information and service processes.
Rule-Based Chatbots vs. NLP Chatbots vs. LLM-Powered Chatbots
These approaches can overlap, but they solve conversational problems in different ways. A business should choose based on the task’s complexity, the acceptable risk of an incorrect response, and the level of flexibility users need.
| Approach | How it works | Best suited for | Main limitation |
| Rule-based chatbot | Follows predefined rules, menus, and decision trees | FAQs, guided forms, predictable workflows | Struggles with unexpected phrasing and open-ended questions |
| Traditional NLP chatbot | Uses models such as intent classifiers and entity extractors, often with dialogue rules | Support requests, structured tasks, intent-based routing | Needs suitable training examples and careful handling of unfamiliar requests |
| LLM-powered chatbot | Uses a large language model to interpret input and generate responses, often with tools or retrieval | Open-ended questions, summarization, flexible conversation | Can produce unsupported answers and requires stronger validation and controls |
A rule-based chatbot may be the best choice for a small set of predictable tasks. A traditional NLP chatbot can offer more flexibility while keeping the possible intents and responses relatively controlled. An LLM-powered chatbot can handle varied phrasing, but the surrounding application still needs to manage data access, business rules, and actions safely.
These approaches are not mutually exclusive. A system can use an LLM to understand a request, a conventional classifier for a specific decision, deterministic rules to enforce policy, and a backend API to execute an authorized action.
For a broader comparison of conversational systems, see chatbots vs. copilots vs. real agents.
Where Should NLP Run in a Mobile App: On-Device or in the Cloud?
NLP can run directly on a mobile device, on a remote server, or through a hybrid architecture. There is no universally best option; the decision depends on the model, data sensitivity, device capabilities, network conditions, and response-time requirements.
On-device NLP processes input locally. It can reduce the need to send raw text to a server and may support offline functionality. However, mobile devices have limited memory, battery capacity, and processing power, which can restrict model size and complexity.
Cloud-based NLP sends input to a remote service for processing. This approach can support larger models and centralized updates, but it depends on network connectivity and introduces server, data-transfer, and service costs. Sensitive information also needs appropriate protection in transit, at rest, and during processing.
Hybrid NLP divides work between the device and the cloud. A mobile app might handle speech capture or basic classification locally, then call a backend service for complex reasoning or access to business data.
| Consideration | On-device | Cloud-based | Hybrid |
| Network dependency | Lower for supported tasks | Usually requires connectivity | Depends on the task |
| Model capacity | Constrained by device resources | Can support larger models | Can balance local and remote processing |
| Data handling | Can keep some input local | Requires secure transmission and processing | Depends on which data leaves the device |
| Updates | May require model or app updates | Centralized model updates are easier | Updates may be needed in both places |
| Cost profile | Device resources and model maintenance | Infrastructure and inference costs | More complex architecture and monitoring |
Businesses should evaluate real performance on supported devices and networks rather than assuming that local processing is always faster or that cloud processing is always more accurate. They should also define how data is retained, whether users need to consent to processing, and how the system behaves when a service is unavailable.
How to Build and Evaluate an NLP-Powered Mobile App
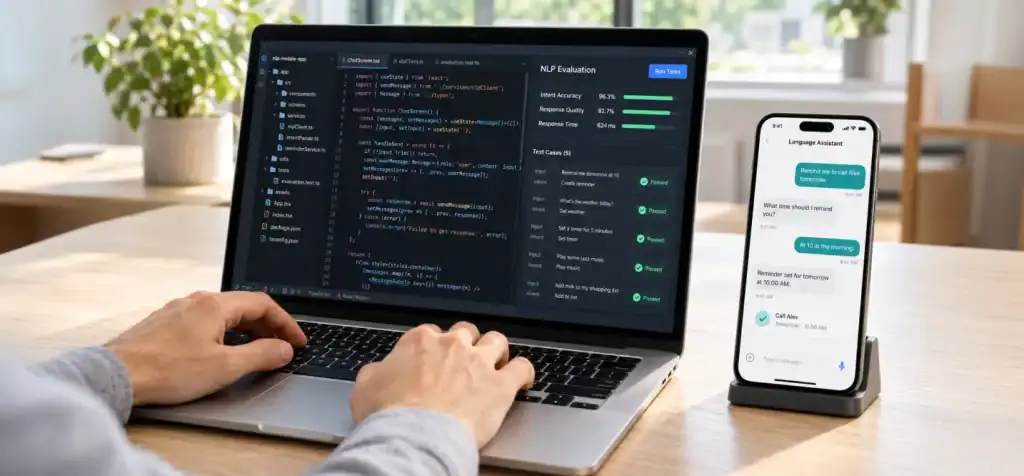
Building an NLP feature starts with the user problem, not the model. A chatbot for tracking orders has different requirements from a sentiment analysis system that reviews thousands of customer comments.
1. Define The Use Case and Success Criteria
Specify what the feature should do, who will use it, and what a successful outcome looks like. For example, a support chatbot might need to resolve common delivery questions, while a sentiment system might need to identify negative feedback about a particular feature.
Define failure cases as well. Decide when the app should ask for clarification, return no result, or hand the conversation to a human.
2. Choose a Model or Service
Depending on the use case, the solution may use a pretrained NLP model, a third-party API, a fine-tuned model, or a custom model trained on labeled examples.
A pretrained model can reduce initial development work, but it still needs evaluation against the app’s real inputs. Fine-tuning may help when a model needs to handle domain-specific language or a particular classification task. A custom model may be appropriate when data, control, performance, or deployment requirements justify the additional work.
The choice should account for supported languages, inference latency, privacy requirements, operating costs, and the effort required to maintain the system.
3. Prepare Representative Data
Data requirements vary by task. Intent classification and sentiment analysis commonly use labeled examples, while some pretrained models can perform useful tasks without task-specific training.
A training or evaluation dataset should reflect the language people actually use, including spelling mistakes, abbreviations, short messages, and relevant domain terminology. It should also include ambiguous examples and cases the model should reject or escalate.
Keep training, validation, and test data appropriately separated. Where possible, avoid leakage from duplicate or near-duplicate examples across splits, since it can make results appear better than real-world performance.
4. Integrate the NLP Model With the Mobile App
The mobile interface is only one part of the implementation. The backend may need to authenticate users, retrieve account or product information, apply business rules, log failures, and connect the model to other systems.
A production architecture should also address secure API access, rate limits, error handling, timeouts, monitoring, and fallback behavior. For sensitive or consequential actions, validate the model’s output and enforce authorization in application code.
If the project requires specialized expertise across app engineering, AI integration, and deployment, this guide on choosing an AI chatbot development company can help structure the evaluation.
5. Measure Real-World Performance
A model that performs well in a test environment may still struggle with actual user messages. Evaluate the complete experience, not just the model’s raw output.
| Capability | Useful metrics or checks |
| Intent classification | Precision, recall, F1 score, and confusion between important intents |
| Named entity recognition | Entity-level precision, recall, and F1 score |
| Sentiment analysis | Per-class precision and recall, F1 score, and error analysis |
| RAG and semantic search | Retrieval relevance, answer support, and faithfulness to retrieved sources |
| Chatbot workflows | Task completion, escalation rate, incorrect actions, and user feedback |
| Mobile performance | Response latency, crash rate, battery use where relevant, and behavior under poor connectivity |
For classification tasks, accuracy alone can be misleading when some categories are much more common than others. Google’s machine learning guide to classification metrics explains how precision, recall, and F1 provide additional insight into model performance.
Finally, monitor the system after release. Language, user expectations, products, and policies change. Review failure cases, update data and evaluation sets, and test model changes before rolling them out broadly.
What Are the Limitations of NLP in Mobile Apps?
NLP can make mobile interactions more natural, but it cannot eliminate ambiguity or guarantee that every interpretation is correct. Its limitations should shape the product experience from the start.
- Ambiguous language: A message may have multiple meanings, particularly without conversation history. The app may need to ask a clarifying question.
- Sarcasm and mixed sentiment: “Great, another failed payment” contains words that appear positive but express frustration. Models can misread such cases.
- Language and dialect variation: Performance may vary across languages, regional expressions, accents, code-switching, and domain-specific vocabulary.
- Incomplete or inaccurate input: Speech recognition errors, typos, and missing details can lead to incorrect downstream results.
- Hallucinations in generative models: LLMs may generate plausible but unsupported information. Retrieval, constraints, validation, and escalation reduce risk but do not eliminate it.
- Privacy and security: Messages may contain personal information. Data collection, access controls, retention, encryption, and third-party processing need careful review.
- Latency and connectivity: Remote model calls can introduce delays or fail when the network is unreliable. Large on-device models may also be slow on less capable hardware.
- Cost and maintenance: Model inference, API usage, monitoring, evaluation, and ongoing updates can add operational expenses.
The right response to these limitations is not always a more complex model. Clearer user flows, reliable data sources, restricted permissions, sensible fallbacks, and human review can often improve the experience more than changing the model alone.
How Much Does It Cost to Build an NLP Chatbot?
The cost of an NLP chatbot depends on its scope, model choice, integration requirements, data needs, and production standards. A basic FAQ chatbot using predefined responses is a different project from a multilingual assistant that retrieves customer records, uses an LLM, and completes authorized actions.
Major cost drivers include:
- Feature complexity: Intent recognition, sentiment analysis, multilingual support, voice interaction, and multi-step conversations each add requirements.
- Model and infrastructure: Third-party APIs, hosted models, cloud infrastructure, or on-device deployment have different cost profiles.
- Data preparation: Cleaning, labeling, evaluating, and maintaining domain-specific datasets can require significant effort.
- Backend integrations: Connecting CRM, payment, inventory, order management, or support systems adds engineering and testing work.
- Security and compliance: Sensitive data and regulated use cases may require additional controls, audits, and documentation.
- Testing and maintenance: Monitoring, model evaluation, bug fixes, updates, and infrastructure management continue after launch.
A useful estimate should separate initial development from recurring costs such as model inference, hosting, monitoring, and ongoing support. It should also include a plan for handling failed requests and human escalation.
Businesses planning a broader mobile product can explore an AI mobile app development company when evaluating the engineering required to bring NLP features into a production application.
Conclusion
NLP in mobile apps helps businesses move beyond rigid menus and keyword matching toward interfaces that can interpret requests, analyze feedback, and respond in more natural ways. Chatbots can use intent classification, entity extraction, dialogue management, and retrieval to support users, while sentiment analysis can reveal patterns across reviews and customer conversations.
The key is to match the technology to the task. Some features need a small classifier or a rule-based workflow; others benefit from LLMs, semantic search, or retrieval-augmented generation. Each approach needs appropriate data, integration, evaluation, and safeguards.
For businesses planning an NLP-powered mobile experience, start with a clearly defined user problem, establish measurable success criteria, and test the complete workflow with realistic inputs. A well-engineered solution should not simply understand language. It should help users complete tasks reliably, protect their data, and give the business useful results.
Build a Mobile App That Listens, Understands, and Responds
Contact Us
Frequently Asked Questions
1. What is NLP and how does it work in mobile apps?
Natural language processing (NLP) enables software to analyze human language in text or speech. In mobile apps, it can process input, identify intent and entities, retrieve information, classify sentiment, or generate a response. The workflow depends on the feature and may involve a model running on the device, a remote service, or both.
2. How do chatbots understand and respond to user input?
Chatbots process a message to identify its intent and relevant details. They may use conversation history to resolve references, retrieve information from a connected system, and select or generate a response. Reliable chatbots also validate actions, ask for clarification when necessary, and escalate requests they cannot handle safely.
3. What is sentiment analysis and how does it help businesses?
Sentiment analysis estimates the opinion or emotion expressed in text, often classifying it as positive, negative, or neutral. Businesses use it to analyze app reviews, support conversations, surveys, and customer feedback. Aspect-based sentiment analysis can go further by linking opinions to specific features, such as delivery, pricing, or usability.
4. Can you build NLP apps without machine learning expertise?
Yes. Developers can use pretrained models, hosted NLP APIs, and managed AI services without training a model from scratch. However, production applications still need appropriate integration, testing, data protection, monitoring, and error handling. Specialized machine learning expertise becomes more important when the task requires custom models, domain-specific evaluation, or advanced optimization.
5. What is the difference between rule-based and AI chatbots?
Rule-based chatbots follow predefined rules, menus, and decision trees. AI chatbots use NLP models to interpret varied user input and may classify intent, extract entities, or generate responses. Rule-based systems are often predictable for narrow workflows, while AI chatbots can handle more varied phrasing but need stronger evaluation and safeguards.
6. How do language models like ChatGPT work?
Large language models are trained on large text datasets to learn patterns in language. When prompted, they process the input and generate output based on the learned patterns and the context provided. Their responses can be fluent without being factually correct, so applications that need reliable answers should use appropriate sources, validation, and safeguards.
7. What are the limitations of NLP in mobile apps?
NLP systems can misinterpret ambiguous wording, sarcasm, unfamiliar dialects, or incomplete input. Generative models may also produce unsupported answers. Other concerns include latency, network dependence, privacy, model costs, and performance differences across languages or devices. Testing with representative user data and providing clear fallback paths helps manage these limitations.
8. How much does it cost to build an NLP chatbot?
There is no single price that applies to every NLP chatbot. Cost depends on the number of features, model and hosting choices, data preparation, mobile and backend integrations, security requirements, and ongoing maintenance. A useful estimate should define the chatbot’s tasks, expected usage, integration scope, and performance requirements before assigning a budget.
9. What data is needed to train an NLP model?
The data depends on the task. Intent classification typically uses example messages labeled with intents, while sentiment analysis uses text labeled with sentiment categories or scores. Named entity recognition needs examples annotated with relevant entities. Pretrained models may work without task-specific training data, but representative evaluation examples are still essential to measure performance.
10. How accurate are sentiment analysis models in production?
There is no universal accuracy rate for sentiment analysis. Performance varies with the model, language, domain, quality of labels, and complexity of the text. A model may perform well on clear positive and negative reviews but struggle with sarcasm, mixed opinions, or rare expressions. Businesses should test on representative data and track per-class precision, recall, F1 score, and real-world errors.